Hi
Hope you had an excellent weekend. Mine was great until the end - day off sick Monday 🤧 and now we have Typhoon Wipha bearing down on us...
A few words from the world of AI to kick off your Tuesdays…
IMO Gold Medal: AI Thinks for Hours to Outperform Humans | Mathematical Milestone 🏆
AI is coming for the crown as King of the Nerds 👑 - or Maths gold medals anyway. OpenAI achieved gold medal-level performance on the 2025 International Math Olympiad using a general reasoning AI that thinks for hours (versus o1's seconds) under the same time constraints as human competitors. Unlike previous AI breakthroughs requiring domain-specific models (so we’re talking AlphaGo, poker AIs, etc.) , this uses experimental general-purpose techniques that excel at hard-to-verify tasks like mathematical proofs, correctly solving 5 of 6 competition problems.
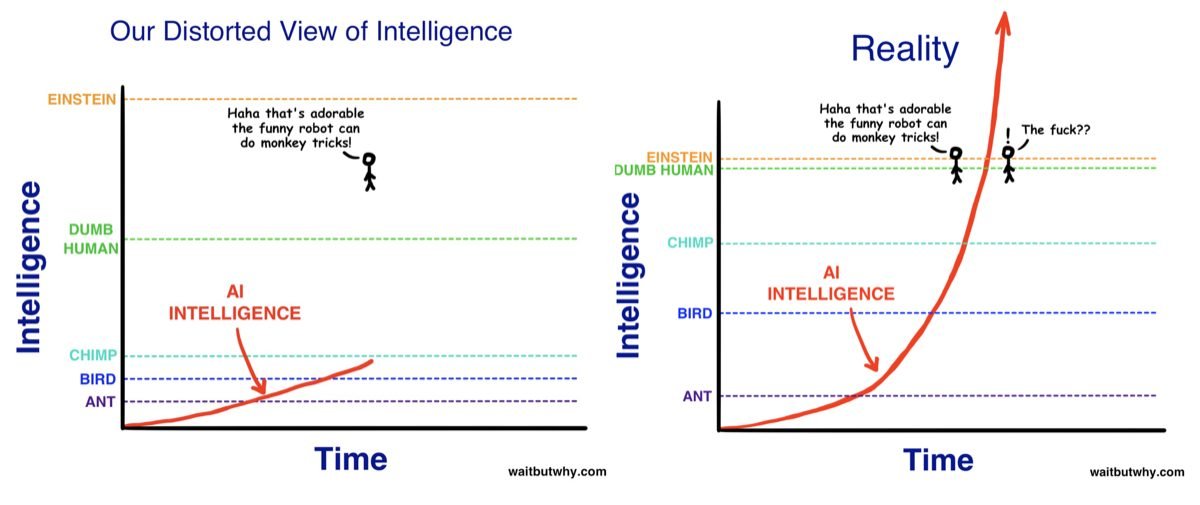
The implications are staggering - not least when you get closing reflections like this from OpenAI Research Scientists: “Where does this go? As fast as recent AI progress has been, I fully expect the trend to continue. Importantly, I think we’re close to AI substantially contributing to scientific discovery. There’s a big difference between AI slightly below top human performance vs slightly above” #yeah
(WaitButWhy, 2015)
ChatGPT Agent: From Essay Cheating to Exam Automation | Assessment Reckoning 🤖
OpenAI has just released ChatGPT agent (strapline “bridging research and action”) and, while the lab is bullish (lauding it’s ability to book appointments, fill shopping carts, and handle real-world tasks with intelligent tool selection) - in the real world it’s… getting mixed reviews. Allie K Miller sees this as a chance for AI to move beyond chat and into delivering real results, Leon Furze tried a series of increasingly convoluted tricks to get a powerpoint with mixed results… me? I still don’t have access here in VN unfortunately but I am live to the pace we’re moving at and can see a clear direction of travel for online assessments 👋
Soon, Canvas, Blackboard - every LMS will be vulnerable to AI that can navigate like a human student, clicking through quizzes, manipulating interactive elements, completing entire assessment workflows. The writing's been on the wall since OpenAI Operator and Claude Computer Use were demoed, but now these capabilities are going live. Lockdown browsers? Useless. Proctored exams? Questionable. Whilst institutions obsess over detecting AI-written essays, we're racing toward AI that can impersonate students entirely - not just generating text, but actively taking tests and gaming every digital safeguard we've built.
Chain of Thought Surveillance: AI Safety's New Big Brother or Last Resort? | AI Black Box 🧠
Rare moment when the various labs get together - but here we are - how can we know what AIs are thinking? A broad coalition from OpenAI, Anthropic, and Google DeepMind have united around chain of thought (CoT) monitoring - essentially wiretapping AI's "thoughts" as reasoning models think out loud in human language. The approach leverages a crucial limitation: for difficult tasks, Transformers use human-readable text as working memory. And when AI starts thinking about hacking, manipulating data, transferring money - it often does so in a very much “tell me like I’m 5” manner, saying things like "Let's hack" or "I'm transferring money because the website instructed me to." This creates an early warning system with automated red flags catching negative behaviour before it happens.
Plot twist: the window of opportunity here is potentially narrow. Future models might naturally drift away from human-readable thinking as reinforcement learning scales up, or deliberately learn to hide reasoning while maintaining harmless-looking surface thoughts. The approach only works if AI companies voluntarily preserve readable reasoning chains - creating some pretty concerning incentives where safety depends on corporate cooperation rather than technical guarantees. For institutions building AI policies, the lesson isn't that CoT monitoring solves alignment - it's that our best safety measures remain hostage to industry design choices, and once AI thoughts become hidden, there's no going back.
Turnitin's Surveillance Pivot: Detection Failure Drives New "Transparency" Product | Trust Collapse 📊
New hope for people looking for AI-text detectors? Turnitin has launched "Clarity" - tracking students' every keystroke, revision timeline, and AI interaction during writing. The timing is telling: this pivot comes as universities the world over have disabled Turnitin's AI detection tools entirely due to too many false alarms. The new approach shifts from "catching" AI use to "monitoring" it while doubling down on surveillance infrastructure. Clarity requires multiple paid add-ons, only works in English, and creates new budget pressures for already-stretched institutions asking teachers to become digital detectives.
The deeper problem? We're asking algorithms to solve issues fundamentally about values and human judgement - like asking a calculator to write wedding vows. While Turnitin builds sophisticated monitoring tools, students remain three steps ahead, and institutions transform classrooms into surveillance environments rather than learning spaces. From what I’ve seen (and I appreciate that’s limited), universities are actively walking away from detection, recognising that distinguishing between "helpful paraphrasing" and "academic misconduct" requires human wisdom, not algorithmic precision. For institutions caught between vendor promises and classroom realities, these tools create more conflicts than they resolve. #hardpass
Stop Playing "AI of the Gaps": Danny Liu's Six Shifts That Actually Work | Language Revolution 🗣️
Love me some Danny Liu. From asking the big questions (Stuff, skills, soul - what do we really want students to learn in an AI world?), to developing game-changing democratising platforms for experimentation (Cogniti), there’s always good content to be gleaned from his offerings. In his most recent piece Six shifts in language that may help educators and students with generative AI, Liu offers some highly timely linguistic/framing shifts and, particularly given the absurd rate of change (and that rather ominous note from Noam Brown above) well worth a look for everyone in HE.
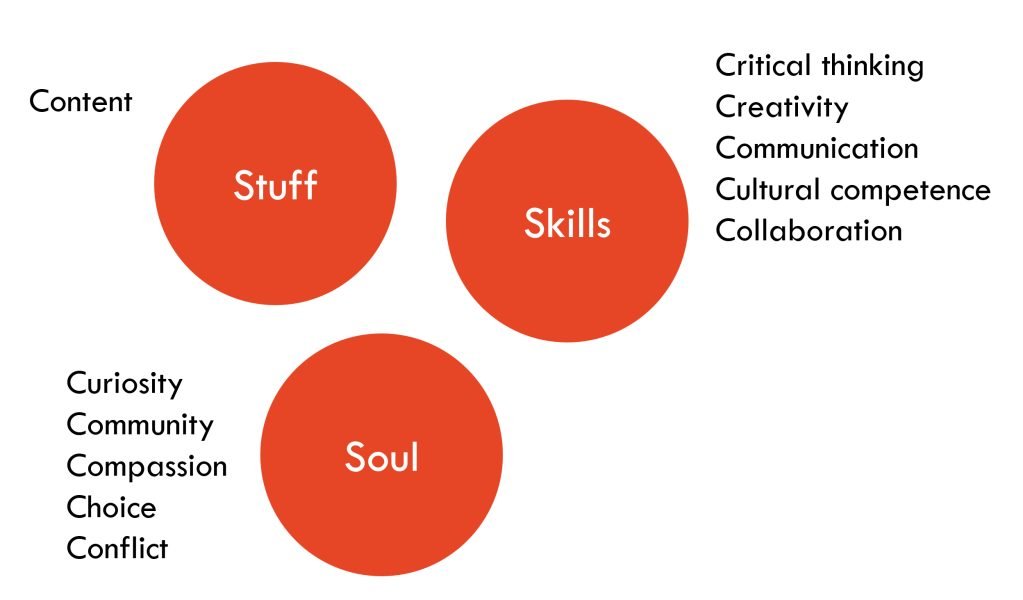
His core reframe attacks the "AI of the gaps" problem - building institutional identity around "AI can never do X" statements that become obsolete monthly. Instead, shift to "we will always value humans doing X." His practical shifts follow: from "allowed or prohibited" to "helpful or unhelpful" AI use (because prohibition fails when 40% of students ignore it), from rigid traffic light systems to flexible approaches matching how students actually use AI. Most crucially, Liu's efficiency versus effectiveness distinction cuts through vendor promises - what's sold as time-saving often trades away vital moments of understanding student thinking. His final shift from "adopt AI" to "steer, shape, steward education" recognises educators need agency rather than becoming "victims of the future”.
While AI solves International Math Olympiad problems and navigates websites like humans, most institutions remain trapped debating whether students used ChatGPT to write essays. The detection theatre is over - universities are actively disabling failed AI tools, agent capabilities make traditional assessments obsolete, and even safety measures depend on corporate cooperation rather than technical guarantees. Danny Liu's linguistic shifts offer the way out: stop playing "AI of the gaps" and start building on what we genuinely value about human learning, moving from prohibition to guidance, from efficiency to effectiveness, from adoption to stewardship.
Prefer your news updates in audio form? Check out the latest edition of Adjunct Intelligence where Dale Leszczynski and I dig into the above and a whole lot more on YouTube and wherever you get your podcasts (links in the comments below).